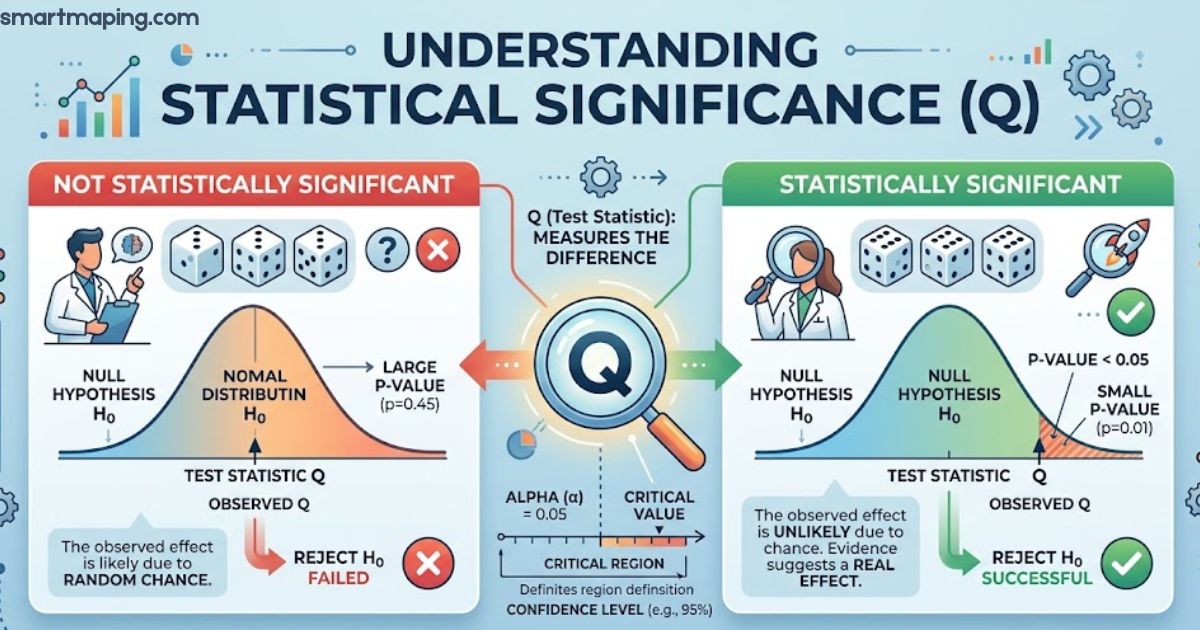
Understanding q significant starts with one simple idea: a p-value is an area in the tail of a distribution that shows the odds of a result happening by chance. Researchers use significance testing to check whether a finding shows a real effect or just random noise.
Small samples make things tricky. In genomics, scientists run hundreds of tests or even thousands of tests, so false positives pile up. The False Discovery Rate, or FDR, solves this, and a Q-value is an adjusted p-value built on it, so q-values matter.
Cochran’s Q test checks a dichotomous dependent variable across three or more related groups, so it works like a one-way repeated measures ANOVA but for yes/no outcomes instead of a continuous dependent variable. It also extends McNemar’s test, and I find it handy for longitudinal study designs and multiple trials.
A statistically significant result shows that differences in proportions exist. Because it is an omnibus test, it cannot name the specific groups that differ, so you follow up with a post hoc analysis. A non-statistically significant result means the proportions match, so skip that step.
What is a Q significant and value?
A Q-value is a p-value adjusted for the False Discovery Rate. It reflects the proportion of false positives you expect, and it helps most with small samples in genomics, where researchers run hundreds or thousands of tests. It also respects the number of tests, and FDR guides the whole process.
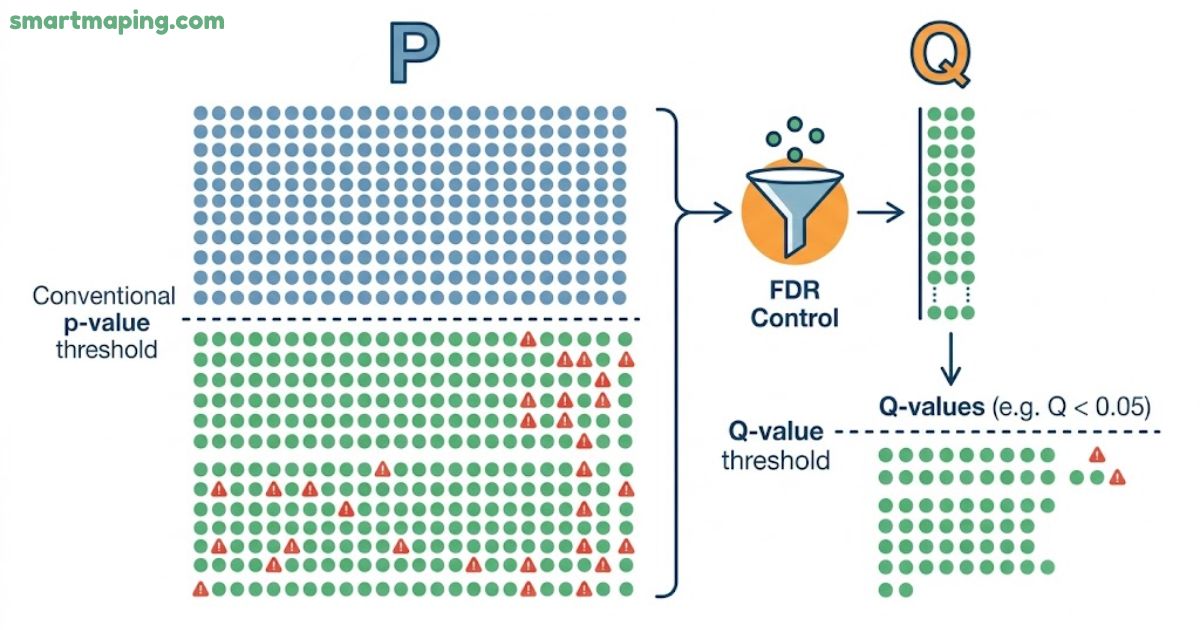
A p-value of 5% means 5% of all tests can give false alarms, so 1600 tests bring about 80 false positives. A q-value of 5% or less counts only results under a threshold, so 5% of significant results turn out false. You often see smaller numbers of false positives, and q significant results deserve more trust for that reason.
Statistical Testing in Q
Q Research Software shows this in practice. Q automates significance testing and picks the most appropriate significance test for your data. Significantly high results appear highlighted in blue, and significantly low results appear marked in red.
You don’t calculate standard errors, confidence intervals, or t-values yourself. The software offers state-of-the-art significance testing tools, including effective sample size adjustments for weights, customizable significance level cut-offs, and false discovery rates. It also runs t-tests with equal variances and unequal variances and handles related groups.
Why are Q-Values Necessary?
Most people set a false positive rate of 5% before they start. That works for one test, but the multiple testing problem hits at 100 tests, which give 5 false results, or 50 for every thousand. Each extra test adds another 5% chance, so by the thousandth test the risk is unavoidable.
Think of a scratch-off lottery where every winning ticket has a 5% chance. Buy 1,000 lottery tickets and you collect 50 winning tickets. Lab tests work the same way, so a small data set with many lab tests produces a false statistically significant result as probability stacks up. Plain p-values mislead there, while q-values keep 5% of significant results at that false-alarm level.
Don’t confuse a Q-value with a plain Q. Q counts the elements in a set that lack a particular attribute. Ask 100 people, and 57 like pizza. The proportion is P=0.57, so Q=0.43, which equals 1 – P.
Tools like SPSS Statistics, Marketsight, Survey Reporter, WinCross, MTabs, and Quantum handle significance testing, but each treats sampling and sample size differently.
Assumptions of Cochran’s Q Test
Cochran’s Q test needs four assumptions; if your data breaks them, pick another statistical test. The first requires one dichotomous variable with two mutually exclusive groups, like perceived safety (safe, unsafe), exam performance (pass, fail), cereal brand (brand A, brand B), seasickness (yes, no), level of exhaustion (low, high), safety helmet use, or skin cream effectiveness (rash, no rash). An intervention such as a two-week revision period sets the pass mark at 60 out of 100 marks, so 59 marks fail.
The second assumption needs one independent variable with three or more categorical related groups, either an ordinal variable or a nominal variable. Likert items on a 7-point scale from strongly agree to strongly disagree count as ordinal, and so do physical activity level with 4 groups (sedentary, moderate) and customers liking a product. Nominal examples include ethnicity (Caucasian, African American, Hispanic) and profession (doctor, nurse, dentist, therapist).
Related groups usually contain the same participants: 10 individuals take a spelling test before, midway, and after a computerised teaching method, also called computerised spelling training. You can also track 20 individuals on task performance under three different lighting conditions: blue lighting, red lighting, and natural lighting, to see whether the colour of the lighting matters.
The third assumption wants a random sample from the population of interest, though real sampling rarely works that cleanly. The fourth needs a big enough sample size to trust the asymptotic p-value; otherwise run the exact version and read the exact p-value instead of the standard Cochran’s Q test. This choice shapes your post hoc test and any q significant verdict on a statistically significant difference in proportions.
FAQs
When should I use significance tests?
Use significance tests when you spot a trend, outlier, or interesting detail in your data set. These findings may come from sampling error or pure coincidence, so a q significant check shows whether the result is noteworthy, a real effect, or chance, and builds confidence.
What problems does significance testing solve?
Significance testing removes guesswork. You quantify your confidence in each result, focus on strong signals, and disregard weak ones with one clear significance test, which keeps q significant decisions simple.
What is the end-point of significance testing?
Significance testing usually ends with a p-value or confidence interval. The p-value shows the probability that a result is significant, so it acts as the end-point, and the confidence interval gives a range for the true result in any q significant report.